Repository navigation
fix: sum, avg, max and min over time with unwrap answer Loki's window on query_range for any range - #740
fix: sum, avg, max and min over time with unwrap answer Loki's window on query_range for any range#740szibis wants to merge 8 commits into
Conversation


… end on query_range, like Loki

Loki evaluates a range query at start, start+step, ... up to and including end, each over (t-range, t]. These functions were read from VictoriaLogs' step buckets as labelled, so the point at end was the bucket after the last line and was missing while the data stops at end. They are now fetched from start-step on anchored step buckets and relabelled onto the evaluation time each closes, as rate and count_over_time over a range equal to the step already are. For a range equal to the step the values are Loki's window; a longer or shorter range keeps the step-sized bucket value.
…r the stddev/stdvar and v1.40 epoch-grid gaps, keep literal-name detection cases meaningful
… and regenerated reports
 github-actions
Bot
added
size/XL

⚪ Performance A/B: no change beyond noise16 shape×range — 16 ⚪ same · results vs Loki: 15 same, 0 new difference(s), 1 pre-existing Every shape is within noise of the base build (±30% and 100 ms). 16 unchanged shape×range (within noise)
Cold (first-run) timings — what a user opening a panel sees
Why these shapes
base |
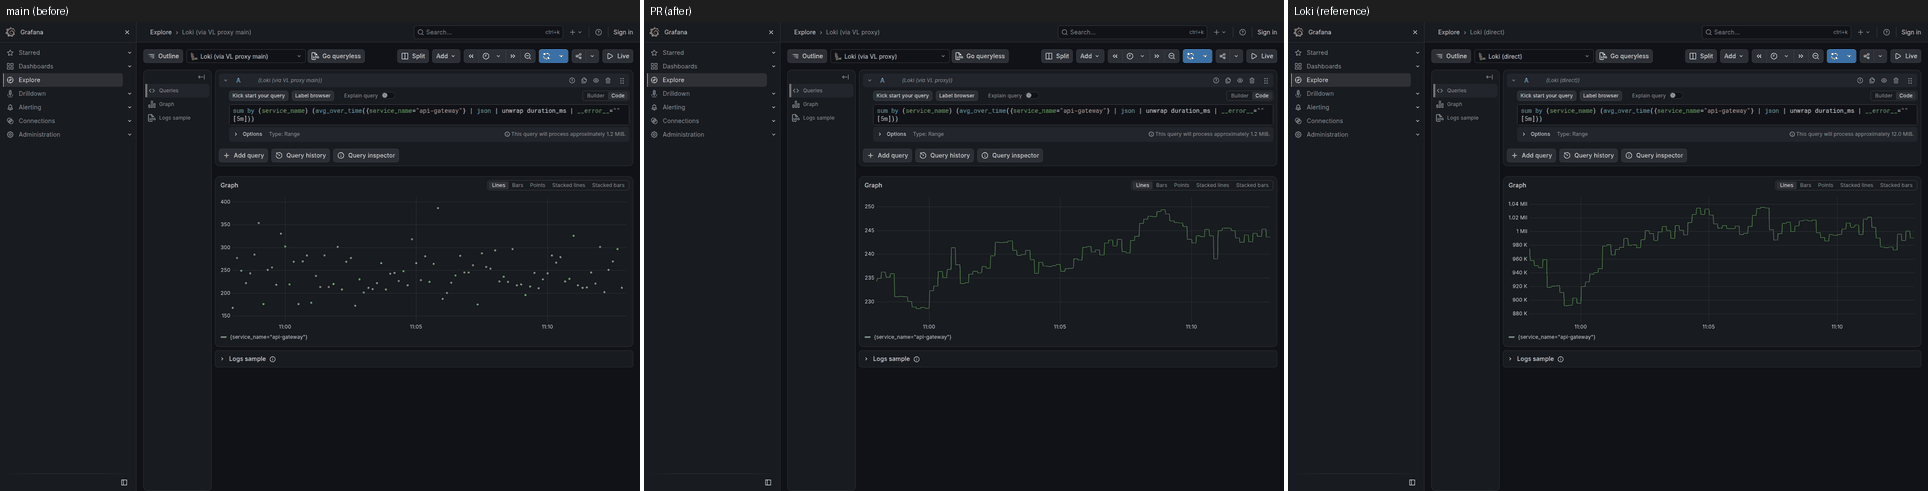
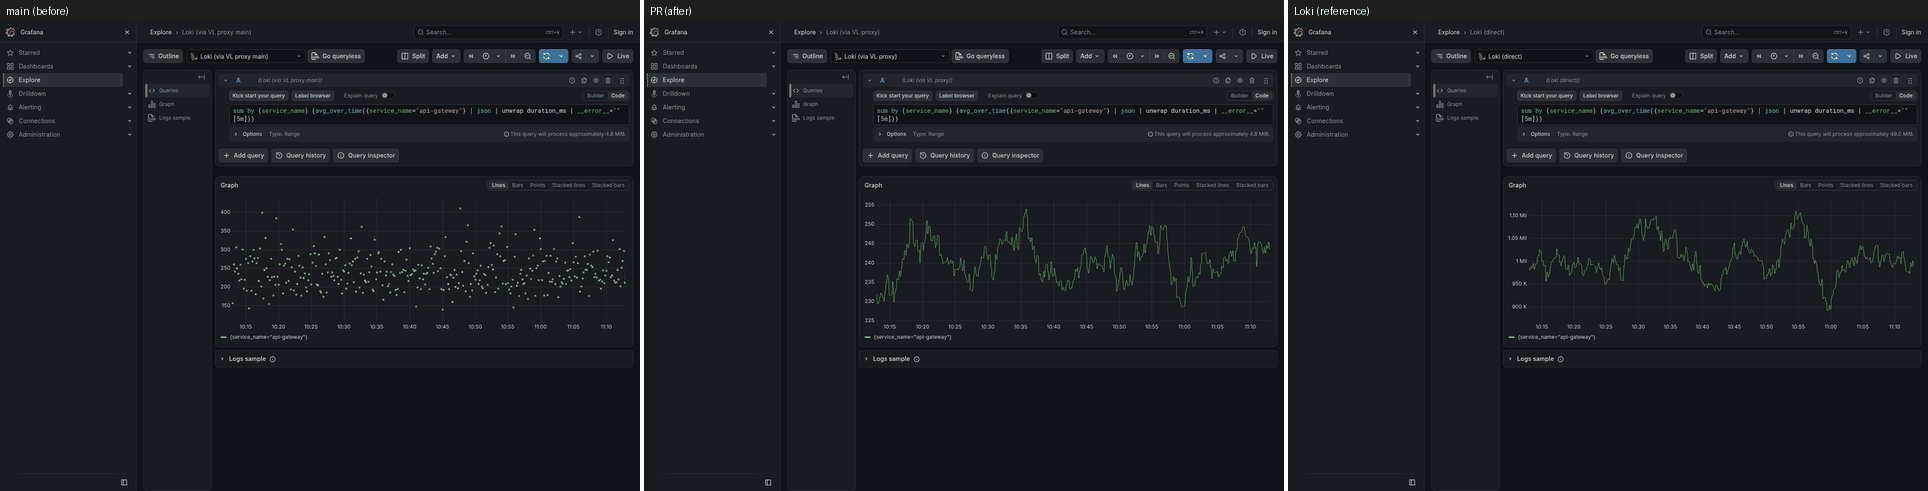
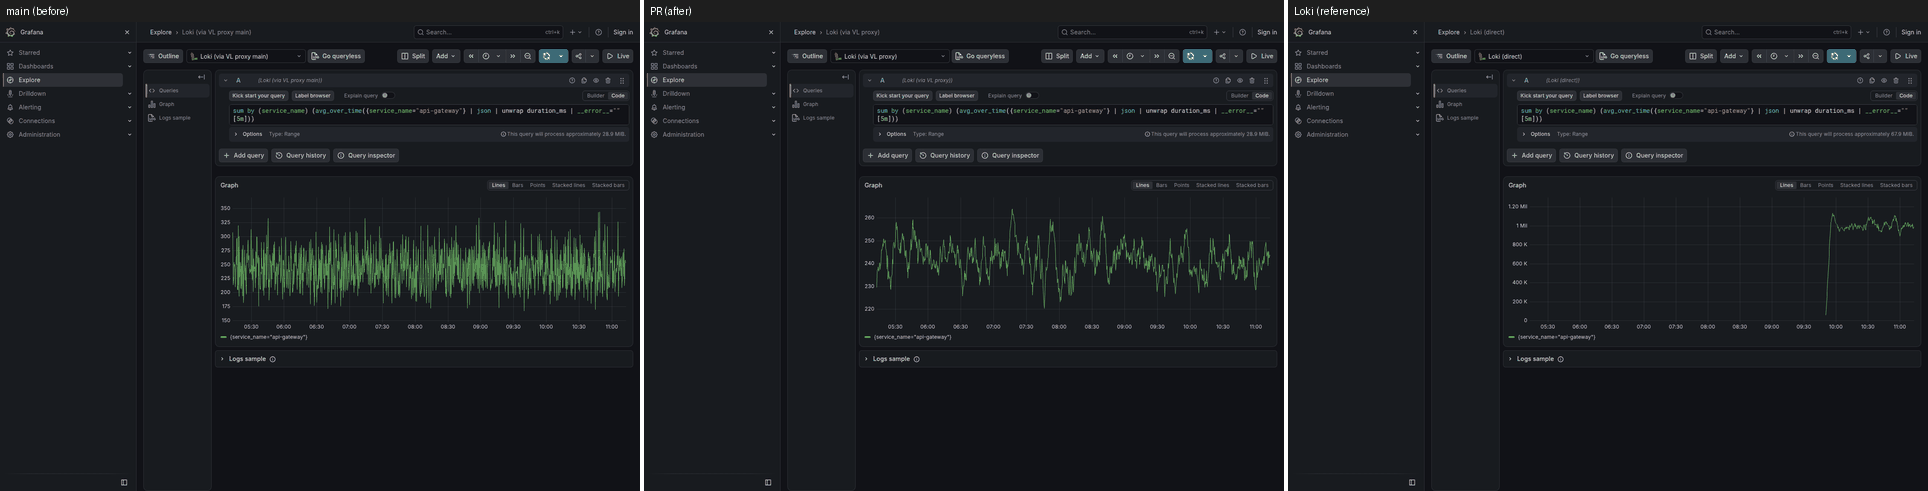
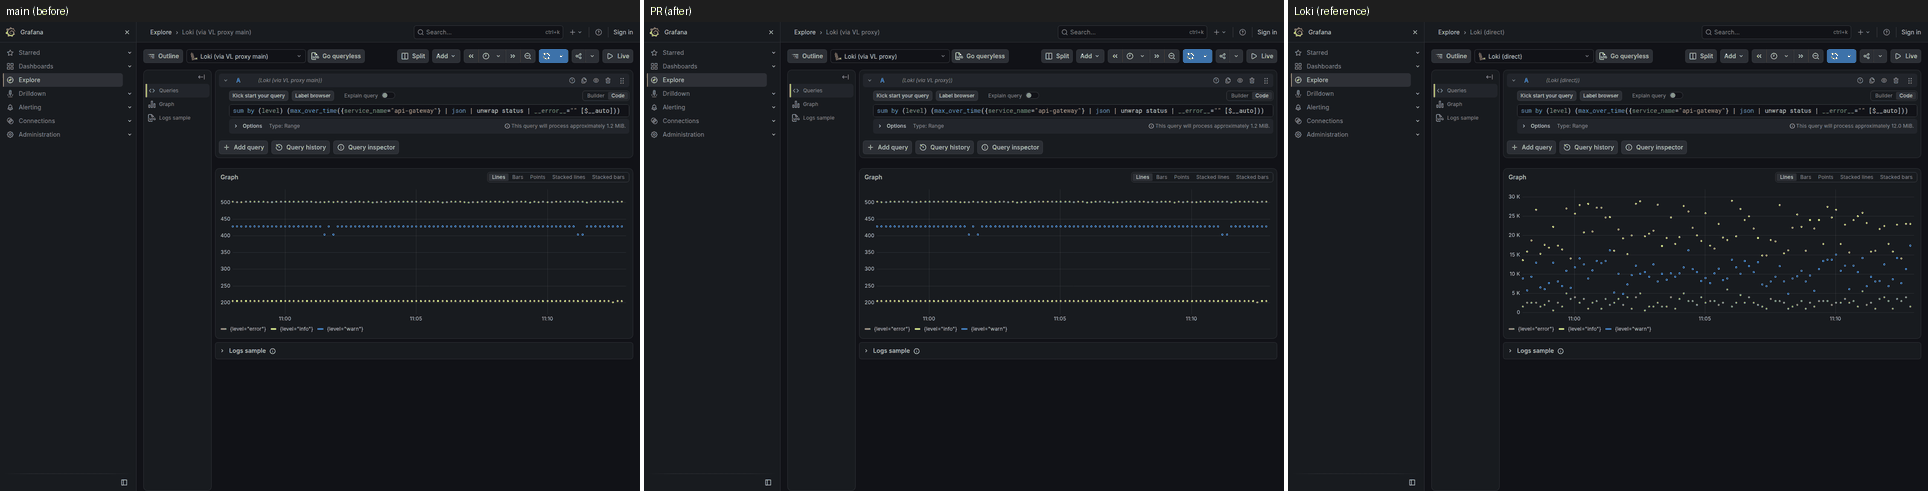
❌ Visual smoke: failedBase Fix proofCaptures of the exact cases this pull request adds or fixes (registry case, base | PR | Loki). The verdict compares the PR with Loki where the base did not match. The gate fails a case unless one capture is fixed or improved, or, beyond the Loki data window, the base failed where Loki and the PR both answered with data (the label does not excuse it; only
explore-unwrap-avg-over-time-sliding-window-15m: still differs
explore-unwrap-avg-over-time-sliding-window-1h: still differs
explore-unwrap-avg-over-time-sliding-window-6h: undecided
explore-unwrap-max-over-time-end-sample-15m: still differs
explore-unwrap-max-over-time-end-sample-1h: still differs
explore-unwrap-max-over-time-end-sample-6h: undecided
Regression check
Gate: a base-vs-PR data difference passes when the PR is closer to Loki, and fails when the PR diverges from Loki or Loki cannot decide it (at a range Loki does not hold, a difference passes when the same page proved it closer to Loki at a shorter range; otherwise label the pull request explore-unwrap-avg-over-time-sliding-window-15m: data differs base vs PR and neither build matches Loki; label the pull request `visual-change-expected` if intended (1):
explore-unwrap-avg-over-time-sliding-window-1h: data differs base vs PR and neither build matches Loki; label the pull request `visual-change-expected` if intended (1):
explore-unwrap-avg-over-time-sliding-window-6h: data differs base vs PR and no Loki data for this range; label the pull request `visual-change-expected` if intended (1)
explore-unwrap-max-over-time-end-sample-15m: data differs base vs PR and neither build matches Loki; label the pull request `visual-change-expected` if intended (1):
explore-unwrap-max-over-time-end-sample-1h: data differs base vs PR and neither build matches Loki; label the pull request `visual-change-expected` if intended (1):
explore-unwrap-max-over-time-end-sample-6h: data differs base vs PR and no Loki data for this range; label the pull request `visual-change-expected` if intended (1)
Core set montages (5): base | PR | Lokidd-fields-1h
dd-landing-1h
dd-service-logs-1h
explore-logs-plain-1h
explore-metric-plain-1h
All montages of this run: |
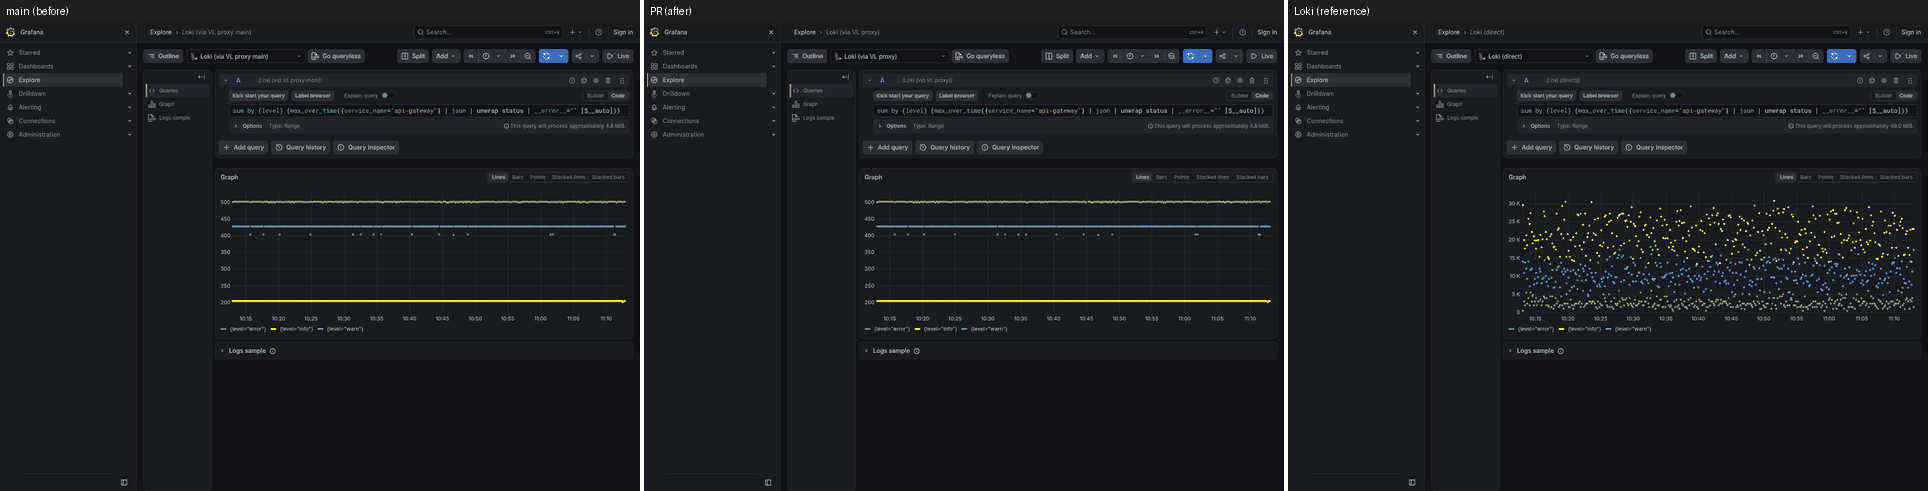
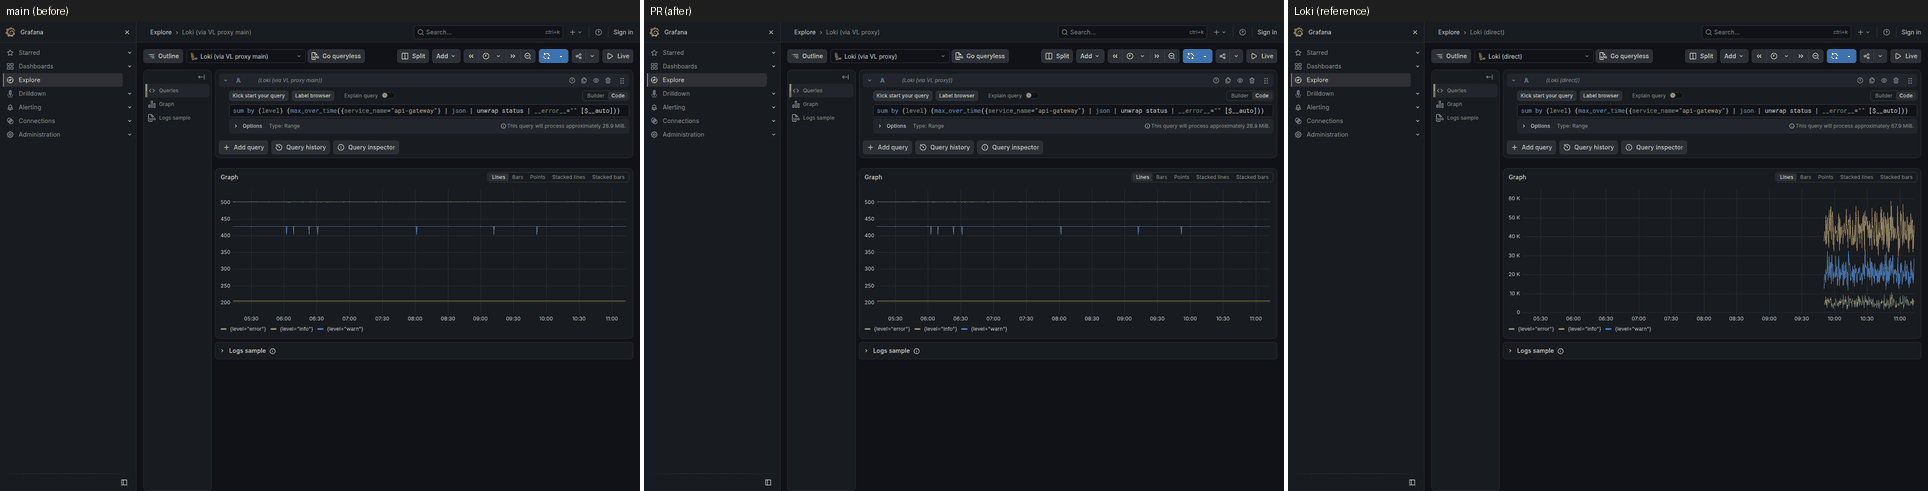
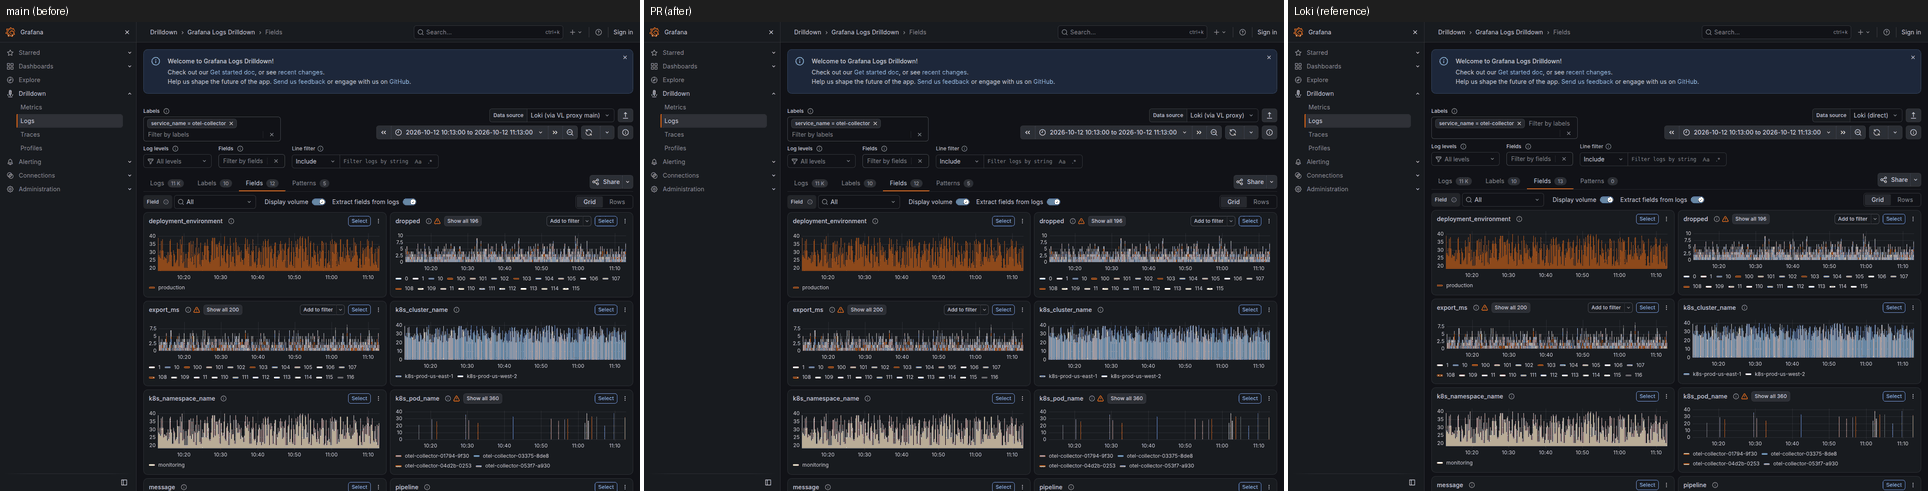
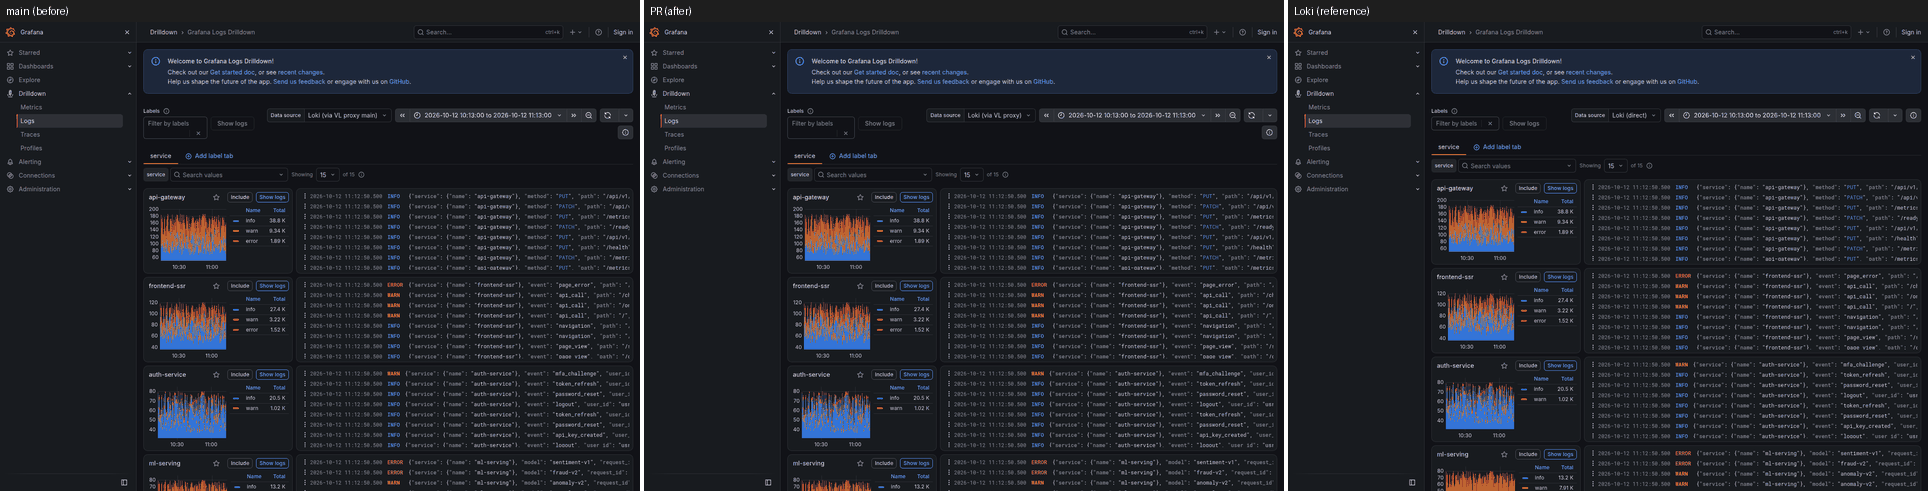
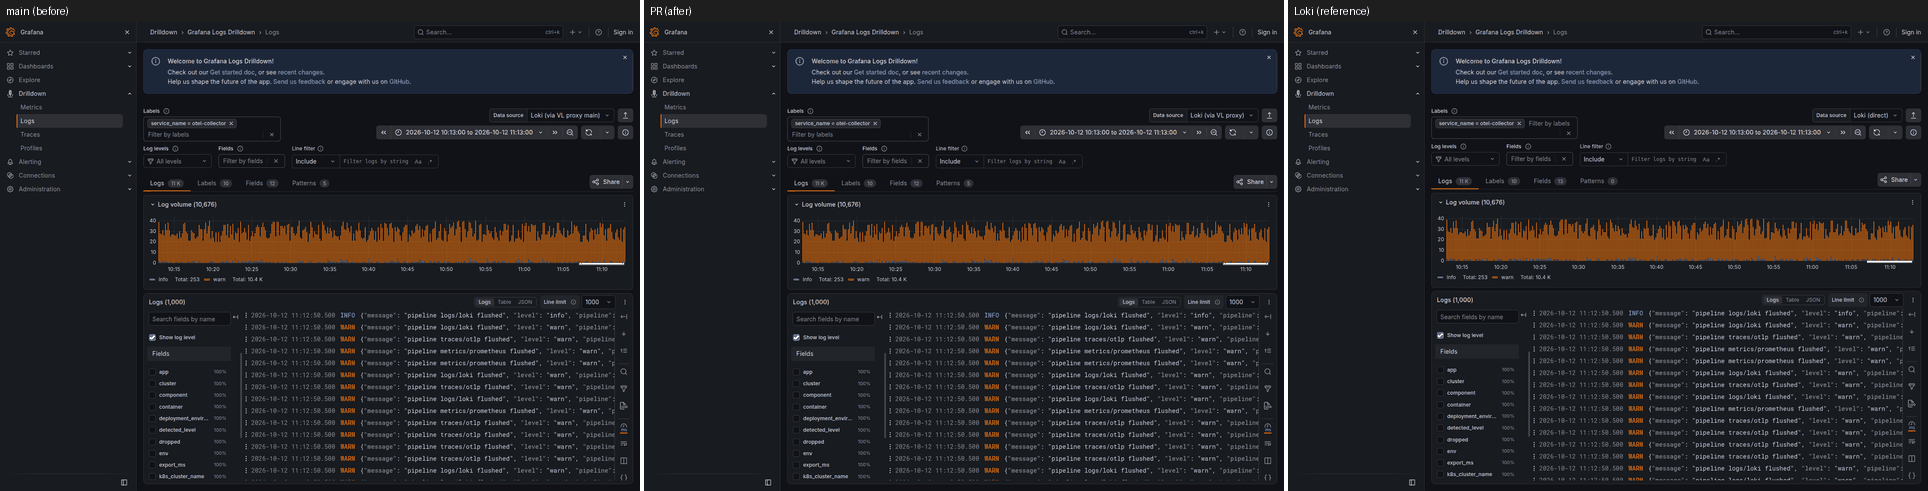
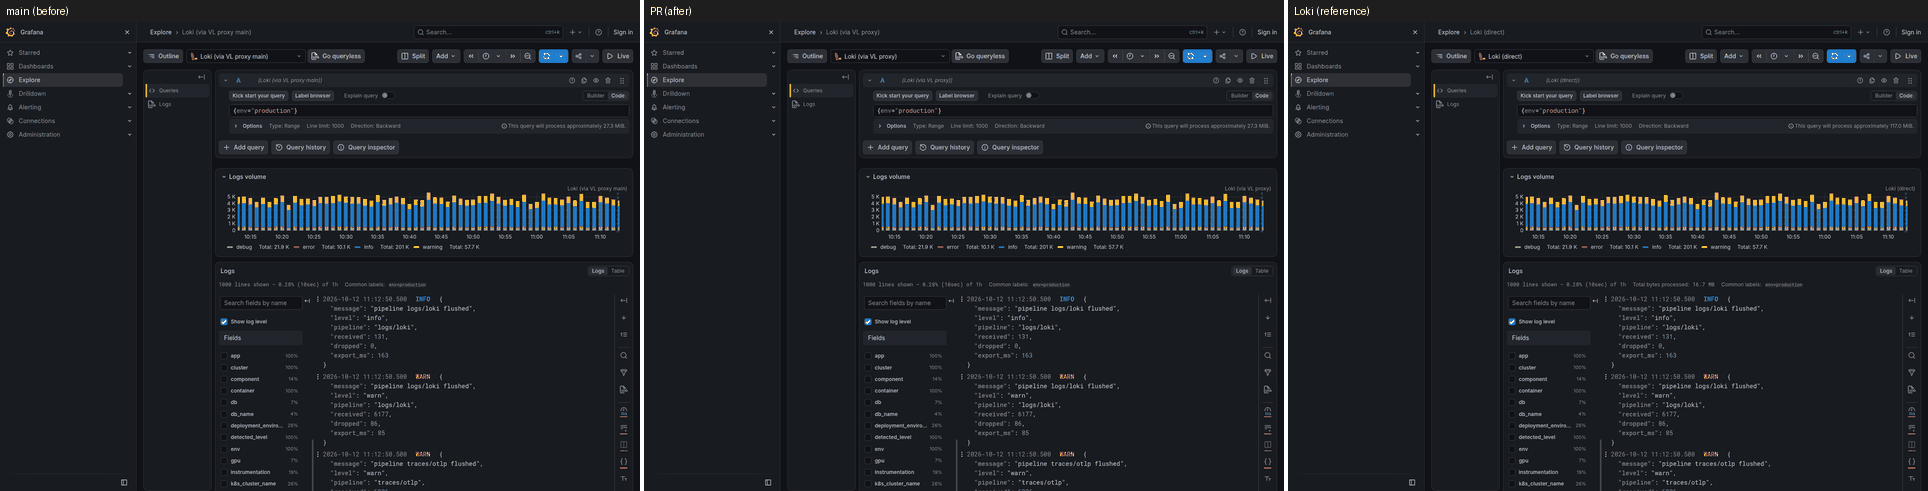
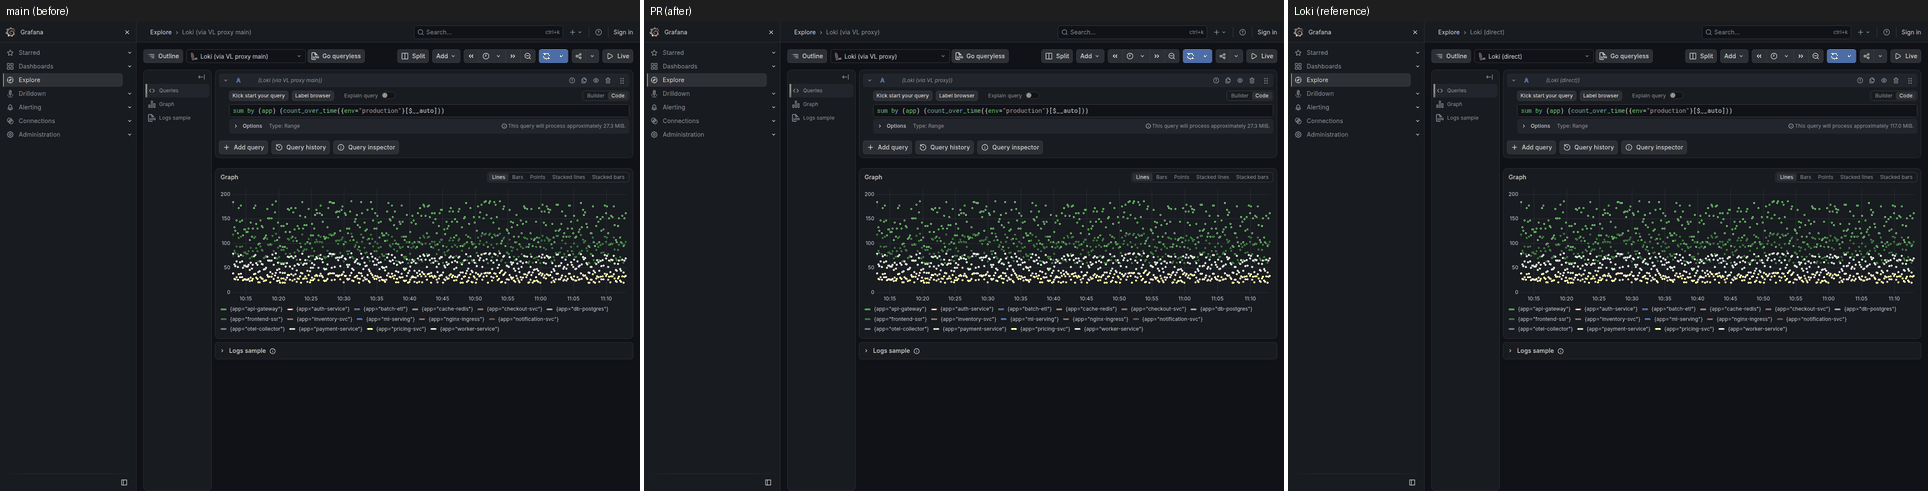
PR Quality ReportCompared against base branch Coverage and tests
Compatibility
Performance smokeLower CPU cost (
State
|
…hich a parser's series identity cannot change
… on query_range for any range

Loki evaluates these functions over (t-range, t] at every step. For a range longer or shorter than the step the proxy answered each point from one VictoriaLogs step bucket, so values were off (about a fifth of Loki's for a 5m range at step 60s) and on sparse data whether a step had a sample followed the bucket rather than the window. VictoriaLogs now returns, per series and per bucket anchored at the request, the sum, max or min of the unwrapped values with their count, and the proxy merges the buckets of each window like the window evaluator already does for rate with unwrap: the sum, the sum over the window's count for avg, the max or the min, with a sample only where the window holds a line. An ungrouped sum of avg, max or min folds the per-stream windows and counts as one series against the series limit. VictoriaLogs before v1.45 with a start off the bucket's epoch grid and more than 11,000 buckets use the raw-row fallback, which reads (t-range, t] for these functions; on those versions that includes a range equal to the step with an off-grid start, which read epoch-grid buckets one step off before. Instant queries, offset handling and a range equal to the step on a supported grid are unchanged.
…fix proof page for unwrap-over-time-range-windows and regenerated reports

Registers the forms the window merge does not answer yet as open rows (an ungrouped sum or a without of avg, max or min over a parser query; an outer aggregation other than sum dropped by the window evaluator), updates the range == step row and the v1.40 epoch-grid row to what the window merge now answers, and adds an Explore page with a 5m range at Explore's step.
…e, which a parser's series identity cannot change

92a58a8 to
c882ee3
Compare
…han the step answer Loki's window

Loki reads each step's sample from (t-range, t]
(pkg/logql/range_vector.go:102-189 batchRangeVectorIterator.Next and load;
the functions at range_vector.go:371-420), and the windows overlap when the
range is longer than the step. statsRateRangeEqualsStepShift read every range
of these functions as the step and shouldUseManualRangeMetricCompat kept them
off the window evaluator, so each point was one VictoriaLogs step bucket
(t-step, t]: sum(sum_over_time({app="payment-service"} | logfmt | unwrap
amount [5m])) at step 60 was 2.00257e+06 where Loki has 9.84307e+06 on the
stack, sum_over_time({app="uw"} | unwrap amount [150s]) at step 2m 725.875
where Loki has 942.125 on the emulated backend, and a line every 4.5 minutes
gave 13 samples in an hour where Loki has 61.

A range longer than the step now goes to the window evaluator that already
answers rate with unwrap (unwrapWindowBuckets). VictoriaLogs returns, per
series, buckets of gcd(range, step) anchored at the request with the partial
aggregate of the converted value (sum, max or min) and the line count
(unwrapBucketAgg; avg keeps the counts to divide by), and the proxy merges the
buckets of each window (mergeUnwrapBuckets) with a sample only where the
window holds a line. VictoriaLogs has no sliding-window stats and one step
bucket cannot hold an overlapping window, so the fold is done in the proxy,
over aggregated buckets only; a grid over 11,000 buckets goes to the raw-row
evaluator bounded by -manual-range-metric-row-limit, which reads the same
window since the previous commit. The route takes only the aggregations the
evaluator applies after the window (unwrapWindowForm): sums by labels or none,
topk and bottomk, label_replace, binary operands, count/min/max/avg by labels
and an outermost labelled without; an outer fold reads under the raw-row
budget (recordFoldBudget, shared with withWithoutFold) and Loki's series
limit applies to its answer. JSON parser queries grouped per stream and line
under an outer aggregation, nested aggregations and an empty without () keep
the step buckets (registered open:
semantics/unwrap-over-time-range-windows-residual-forms). Per-stream series of the route carry detected_level="unknown" for a
stream without a level, as Loki's and rate's do. Ranges up to the step and
instant queries are unchanged; the 7-day E1/E4/E8/E9 shapes ([1m] and [5m] at
step 10m) keep their single phase-filtered step bucket query.

The window phase filter now names the window start modulo the step instead
of the request's start: the same lines, but the query text, and so the stats
extent cache key, stays the same when a window moves by whole steps (one miss
and five partial answers where main had six misses).

Tests: TestUnwrapOverTimeWindowsDifferential (generated rows, edges at +-1ns,
offsets, instant queries, ten query forms, VictoriaLogs v1.49.0, v1.53.0 and
unknown) against a reference evaluator of Loki's windows,
TestUnwrapOverTimeRangeWindowEdgeCases (answers spelled out),
TestUnwrapOverTimeRawWindowBounds, TestUnwrapOverTimeSparseSamplePresence,
TestUnwrapOverTimeUngroupedSumIgnoresSeriesLimit,
TestUnwrapOverTimeResidualShapesKeepStatsBuckets,
TestUnwrapOverTimeShortRangeStaysOnStepBuckets,
TestWindowPhaseFilterKeepsExtentCacheAcrossSteps and the e2e
TestCompat_UnwrapOverTimeRangeWindows (shared fixtures plus lines on every
window edge, range and instant). The differential, edge and presence tests
fail on main for range > step. Pinned answers that read the step bucket move
to the window: five sliding extraction-list goldens and two max without
answers. Brought over from #740 (its tests, adapted to the supported
VictoriaLogs lines), which this supersedes.

…every range and step (#885)

* perf: a range shorter than the step parses only the lines inside a window

Loki reads a step's sample from the window (t-range, t] only
(pkg/logql/range_vector.go:102-189, batchRangeVectorIterator.Next and load):
a line between two windows belongs to no sample. The window evaluator already
kept only those lines with a filter on the stored _time, but it appended the
filter after the whole log pipeline, so VictoriaLogs derived service_name,
unpacked and ran the unwrap gate on every line of the range first.

The filter now follows the query's filters, ahead of every pipe. For
sum by (service_name) (rate({env="production"} | logfmt | unwrap latency_ms [5m]))
over 7 days (step 10m, the daily E3 shape at 13 s cold and warm) half the
lines are parsed; a [1m] range skips nine lines in ten. The pipes the filter
moves ahead of are row-local and never write _time, so the stats see the
same rows and the answer is unchanged. A query holding the derived
detected_level chain keeps the filter after the chain, whose base keys its
remembered presence probe. The unwrap conversion-error lookup carries the
filter once, ahead of the parser, instead of appending a second one.

The conversion-error counter itself is not the cost: the 2026-10-08 A/B ran
E3 at 7d in 13.37 s on main without it and 13.44 s with it, and the metric
sends one stats_query_range and no lookup on clean data.

* fix: sum, avg, max and min over time with unwrap and a range shorter than the step answer Loki's window

Loki reads each step's sample from (t-range, t] only
(pkg/logql/range_vector.go:102-189, batchRangeVectorIterator.Next and load).
With a range shorter than the step the windows are disjoint: most lines belong
to no sample and a step whose window is empty has none. The proxy answered
these functions from VictoriaLogs' anchored step buckets (t-step, t]
(statsRateRangeEqualsStepShift), so
sum by (service_name) (sum_over_time({service_name="api-gateway"} | json | unwrap duration_ms [1m]))
over 7 days at step 10m (the daily E1 shape; E4, E8 and E9 at 7d likewise)
summed ten minutes of lines per point where Loki sums one, and a step with
lines only outside its window had a sample Loki does not.

The stats query now carries the window filter the other range metrics use,
right after the query's filters, so each bucket holds exactly Loki's window and
VictoriaLogs parses only those lines. The unwrap conversion-error check rides
on the same query and counts only the lines inside a window, the only ones Loki
fails on.

TestUnwrapOverTimeShortRangeMatchesLoki compares the four functions with a
reference Loki evaluator over generated rows (edges, empty windows) on three
VictoriaLogs lines, with the error filter, with the conversion check, with a
scalar operand and between two vector operands: all 96 subtests fail before
this change and pass after. No visual fix proof: the visual stack holds Loki
for 1.5h, where Explore's step is seconds and every panel range is longer than
the step. A range longer than the step stays open
(semantics/unwrap-over-time-range-windows).

* fix: the range-vector window excludes its start and includes its end for every function

Loki's batchRangeVectorIterator.load skips `sample.Timestamp <= start` (the
comment in that loop reads "the lower bound of the range is not inclusive")
and keeps samples up to and including the evaluation time, and unwrapped
ranges share that iterator (pkg/logql/range_vector.go:148-189, v3.7.7).
aggregateManualWindow excluded the lower bound only for rate,
count_over_time, bytes_over_time and bytes_rate, so every unwrapped range
function read the sample on windowStart that Loki drops, and answered one
sample high.

Correcting only the lower bound would leave the window open at both ends:
the 1ns extension of the VictoriaLogs fetch, which is exclusive at its end
where Loki is inclusive, was applied to quantile and the log-range functions
alone, so a sample exactly on the evaluation timestamp was never fetched. The
extension is now unconditional, on query_range and on instant queries.

TestLowerBoundIsExclusiveForEveryRangeFunction fails without the change and
passes with it (its quantile subcase uses q=0, which tells {1,2,3} from
{2,3}); TestCompatHelpers_AggregateManualWindow encoded the old bound and is
updated to Loki's.

* fix: sum, avg, max and min over time with unwrap and a range longer than the step answer Loki's window

Loki reads each step's sample from (t-range, t]
(pkg/logql/range_vector.go:102-189 batchRangeVectorIterator.Next and load;
the functions at range_vector.go:371-420), and the windows overlap when the
range is longer than the step. statsRateRangeEqualsStepShift read every range
of these functions as the step and shouldUseManualRangeMetricCompat kept them
off the window evaluator, so each point was one VictoriaLogs step bucket
(t-step, t]: sum(sum_over_time({app="payment-service"} | logfmt | unwrap
amount [5m])) at step 60 was 2.00257e+06 where Loki has 9.84307e+06 on the
stack, sum_over_time({app="uw"} | unwrap amount [150s]) at step 2m 725.875
where Loki has 942.125 on the emulated backend, and a line every 4.5 minutes
gave 13 samples in an hour where Loki has 61.

A range longer than the step now goes to the window evaluator that already
answers rate with unwrap (unwrapWindowBuckets). VictoriaLogs returns, per
series, buckets of gcd(range, step) anchored at the request with the partial
aggregate of the converted value (sum, max or min) and the line count
(unwrapBucketAgg; avg keeps the counts to divide by), and the proxy merges the
buckets of each window (mergeUnwrapBuckets) with a sample only where the
window holds a line. VictoriaLogs has no sliding-window stats and one step
bucket cannot hold an overlapping window, so the fold is done in the proxy,
over aggregated buckets only; a grid over 11,000 buckets goes to the raw-row
evaluator bounded by -manual-range-metric-row-limit, which reads the same
window since the previous commit. The route takes only the aggregations the
evaluator applies after the window (unwrapWindowForm): sums by labels or none,
topk and bottomk, label_replace, binary operands, count/min/max/avg by labels
and an outermost labelled without; an outer fold reads under the raw-row
budget (recordFoldBudget, shared with withWithoutFold) and Loki's series
limit applies to its answer. JSON parser queries grouped per stream and line
under an outer aggregation, nested aggregations and an empty without () keep
the step buckets (registered open:
semantics/unwrap-over-time-range-windows-residual-forms). Per-stream series of the route carry detected_level="unknown" for a
stream without a level, as Loki's and rate's do. Ranges up to the step and
instant queries are unchanged; the 7-day E1/E4/E8/E9 shapes ([1m] and [5m] at
step 10m) keep their single phase-filtered step bucket query.

The window phase filter now names the window start modulo the step instead
of the request's start: the same lines, but the query text, and so the stats
extent cache key, stays the same when a window moves by whole steps (one miss
and five partial answers where main had six misses).

Tests: TestUnwrapOverTimeWindowsDifferential (generated rows, edges at +-1ns,
offsets, instant queries, ten query forms, VictoriaLogs v1.49.0, v1.53.0 and
unknown) against a reference evaluator of Loki's windows,
TestUnwrapOverTimeRangeWindowEdgeCases (answers spelled out),
TestUnwrapOverTimeRawWindowBounds, TestUnwrapOverTimeSparseSamplePresence,
TestUnwrapOverTimeUngroupedSumIgnoresSeriesLimit,
TestUnwrapOverTimeResidualShapesKeepStatsBuckets,
TestUnwrapOverTimeShortRangeStaysOnStepBuckets,
TestWindowPhaseFilterKeepsExtentCacheAcrossSteps and the e2e
TestCompat_UnwrapOverTimeRangeWindows (shared fixtures plus lines on every
window edge, range and instant). The differential, edge and presence tests
fail on main for range > step. Pinned answers that read the step bucket move
to the window: five sliding extraction-list goldens and two max without
answers. Brought over from #740 (its tests, adapted to the supported
VictoriaLogs lines), which this supersedes.

* perf: the window evaluator reads its stats buckets with a pooled JSON parser

collectRangeMetricHitsAux parsed every stats_query_range answer with
fj.ParseBytes, a new parser per call whose value cache is allocated again for
every [timestamp, value] pair. A range longer than the step now sends sum,
avg, max and min over time with unwrap through this read with a value and a
count series per group, so the allocation grew with the answer: a canned
10-series answer of a 24h query at step 60 with a [5m] range allocated
50 MiB per request (main's step-bucket answer 10 MiB). It now takes a parser
from statsQRFJPool, the pool the step-bucket trims use: 18 MiB per request,
1h at step 5s 28 MiB to 9 MiB. Nothing parsed outlives the call (labels are
string copies, values floats).

* fix: the unwrap window route records the fold budget only for a query that folds

The window route of sum, avg, max and min over time with unwrap recorded the
raw-row budget in the request's series limit scope for every query it took,
also a grouped sum that folds nothing; a folded read later in the same
request (the other operand of a binary expression) would then read under that
budget and its error text. It is now recorded only for the outer folds the
route applies afterwards: a series-level aggregation chain
(foldVectorAggregations) and an ungrouped sum of a function VictoriaLogs does
not sum (foldUngroupedSum). A labelled without records it in withWithoutFold.

Two handler tests cover what the differential's emulator cannot:
TestUnwrapOverTimeRangeWindowsNaN sends the counting gate's nan group through
the merged buckets (sum and avg are NaN in the five windows that hold the nan
line, max and min keep the clean value; on main one step is NaN), and
TestRateCounterReadsLokiWindow checks rate_counter's raw window on query_range
and at an instant (0.666667 over (t-1m, t]; main answers 0.333333 with the
old bounds).

* perf: the unwrap window merge groups max by and min by upstream and reads its buckets in place

The corrected range-longer-than-step route cost the proxy 2 to 5 times the
memory of main's (wrong) step-bucket answer. Measured with a canned
10-series VictoriaLogs answer served from memory (the proxy's own cost):
E8 24h 6.8 MiB on main against 11.4 MiB, E4 6h 7.4 against 44.9 MiB.

- max by (L) (max_over_time(...)) and min by (L) (min_over_time(...)), L
  possibly empty: Loki takes the extreme per series over the window and then
  per group (pkg/logql/range_vector.go:405-420; evaluator.go
  VectorAggEvaluator.Next, a NaN giving way in both), which is the extreme of
  the group's lines in the window. unwrapGroupPushdown has VictoriaLogs group
  the buckets by L instead of by stream (or stream and line for a JSON query),
  and the evaluator answers without the JSON fold. Loki's series limit counts
  the groups (pkg/logql/engine.go:530-590 JoinSampleVector), as the read does.
  The translated grouping must be L plus the series identity (_stream, _msg,
  level); anything else keeps the fold. JSON max by and min by of the same
  function leave the residual forms.
- sum, max and min over time read no sample count: VictoriaLogs answers a
  bucket only when it holds a row, so the aggregate's point is the presence
  (the counting gate's nan group still poisons a sum's point); avg keeps it.
- collectRangeMetricHitsAux reads the [ts, value] pairs in place with
  jsonparser and parses only each series' labels (pooled fastjson parser);
  buildHitsRangeMetricMatrix writes the points into a raw JSON array instead
  of an interface pair per point (byte for byte what encoding/json writes);
  the unwrap counter's kept flag leaves the answer in one in-place pass
  instead of three copies (dropKeptFlag, also on the step-bucket route).

Same canned answer, after: E8 24h 4.5 MiB in 1.6k allocations (main 6.8 MiB,
4.2k), E8 1h 2.3 (3.0), E4 6h 4.5 (7.4), avg 24h 7.2 (6.3), the 7-day [1m]
and [5m] shapes 2.9 (3.5, 4.7).

TestUnwrapGroupPushdownMatchesPerStreamFold compares the pushed-down answer
with the per-stream fold's (unwrapGroupPushdownOff) over generated rows,
three VictoriaLogs versions, grouped, ungrouped and under topk, series limits
0 to 3: the same series byte for byte and the same 400s. The differential
gains max by, min by, max and topk of max by over JSON;
TestUnwrapOverTimeRangeWindowsNaN the max by and min by forms;
TestDropKeptFlagMatchesReplacements holds the one-pass removal to the three
replacements. Five sliding extraction-list goldens send the new bucket query;
max(max_over_time(... | logfmt amount, route ...)) now answers Loki's window.

* perf: the window merge moves its bounds with the step and scans bucket pairs directly

buildHitsRangeMetricMatrix searched the window bounds of every step (two
binary searches over the samples, one over the presence, two over the counts
of avg). The windows only move forward with t, so the bounds are now cursors
that only move forward; the prefix sums are built only for the additive
functions that read them. eachBucketPoint reads VictoriaLogs' pairs
`[number,"number"]` with a direct scan instead of two nested jsonparser
walks per pair.

Interleaved benchstat (n=10, canned 10-series answer served from memory,
GOMAXPROCS=2, load average 7 to 9), main / before this branch's perf commits /
now: E8 24h [5m] step 60 3.09 / 5.90 / 2.83 ms, 6.9 / 11.7 / 4.2 MiB; E4 6h
max by 3.14 / 18.66 / 2.85 ms, 7.0 / 42.3 / 4.2 MiB; E8 1h step 5 1.59 /
3.43 / 2.15 ms; avg 24h 3.02 / 7.00 / 5.34 ms, 6.3 / 12.6 / 6.7 MiB; the
7-day range-shorter-than-step shapes 2.25 / 2.29 / 2.01 ms.

* fix: the group push-down names every grouped value by its own label and keeps the fold for detected_level

unwrapGroupPushdown checked that the translation's grouping held the outer
labels as a set and then paired them by position with the user's by-list,
while the collector names each grouped field after the label at its index
(collectRangeMetricHitsAux vlToLoki): a by-list the translation writes in
another order would put a value under the wrong name. Each grouped field is
now named after the label whose name or VictoriaLogs name it is.

A detected_level (or level) grouping keeps the per-stream fold: a stream
without a level is labelled detected_level="unknown" by the per-stream read
(buildMetricSeriesEntry), which a grouping by the stored field does not give.
service_name is pushed down: the translation derives it ahead of the stats
(the coalesce over the stored names), as for sum by (service_name).

TestUnwrapGroupPushdownMatchesPerStreamFold gains max by (app, pod), min by
(pod, app) and max by (detected_level, pod); TestUnwrapGroupPushdownDerivesServiceName
checks the derivation ahead of the grouping. The e2e
TestCompat_UnwrapOverTimeRangeWindows asks max by (app), min by (route) and
max over max_over_time over json and logfmt, on the shared and the edge
fixtures, range and instant.

* perf: the window matrix sizes each series' points from its buckets, not from the range

buildHitsRangeMetricMatrix reserved 32 bytes for every step of the range for
every series that held a point. A query that builds a series per stream before
an outer fold reserved that for thousands of sparse series: the 6h
`sum without (pod) (count_over_time({env="production", ...}[1m]))` shape (W8 of
the unwrap-sum-without set, step 10s, 2161 steps) held 1.9 GB live and
allocated 22 GB per six queries on the stack, a quarter more than main, whose
point slices reserved 24 bytes a step. The process ran at its memory limit and
spent the difference in the collector.

A point needs a bucket in its window, and a bucket lies in the window of at
most window/step+2 evaluation times, so a series cannot hold more points than
its buckets (its presence buckets for count and rate) times that, and never
more than the steps of the range. The reservation is now that bound; a series
that fills every step reserves what it did.

Measured on the A/B stack (6h, step 10s, the same windows, six queries each):
main 2.6 s and 3.3 GB peak RSS, before this commit 5.3 s and 4.1 GB, with it
1.4 s and 0.38 GB. The answers are identical (the same bytes per window).

* docs(changelog): move the unwrap window entries back to Unreleased

---------

Co-authored-by: szibis <szibis@users.noreply.github.com>
Co-authored-by: Igor Kudrin <igor@maestra.io>

|
Superseded by #885, which landed these windows for every range and step (shorter, equal and longer than the step, not a multiple, sliding, json and logfmt, grouped and ungrouped). Its tests were brought over and adapted there, and its registry cases and visual pages are on main, so nothing from this branch is left to land. |

Stacked on #727. This branch contains #727's commits. Merge #727 first; this PR is then rebased and its diff shrinks to its own two commits (48b6aa6, c4e30c5).
Summary
Gap
semantics/unwrap-over-time-range-windows.sum/avg/max/min_over_timewith unwrap computed each point from a single VictoriaLogs step bucket.pkg/logql/range_vector.go:148-189, functions at :371-425).[5m]and 7 for[30s].Fix: VictoriaLogs first, then the proxy.
sum|max|min(__lvp_v)plus a sample count. A bucket is gcd(step, range) wide, or one step with the phase filter when range < step. The unwrap gate and the conversion-error counter ride along.mergeUnwrapBucketsmerges the buckets of each Loki window.sumof avg/max/min folds the per-stream windows. The per-stream buckets are not cut by-max-stats-query-series; Loki counts the folded answer.Tests
TestUnwrapOverTimeWindowsDifferential: 150 subtests failed before the fix. It covers:sum by, per stream,sum,topk,sum withoutand a binary;TestUnwrapOverTimeSparseSamplePresence: the registry's sparse case, 12 failed before the fix.TestUnwrapOverTimeRangeEmitsEndSample(from fix: sum, avg, max and min over time with unwrap answer the sample at end on query_range, like Loki #727) now also checks values.TestCompat_UnwrapOverTimeRangeWindows.Residuals, registered as open rows:
sum/sum withoutof avg/max/min after a parser needs parsed series identity first.Pending before ready
sum(avg_over_time({many streams} | unwrap x [5m]))at 24h/7d. Per-stream buckets are folded there.