


Cut LLM output-token spend without losing information. pith watches a route, replays a sample under cheaper output profiles, has a judge compare every answer with the baseline, and pins a profile only when it is as good as the baseline is with itself. When it is not, pith says so and changes nothing.
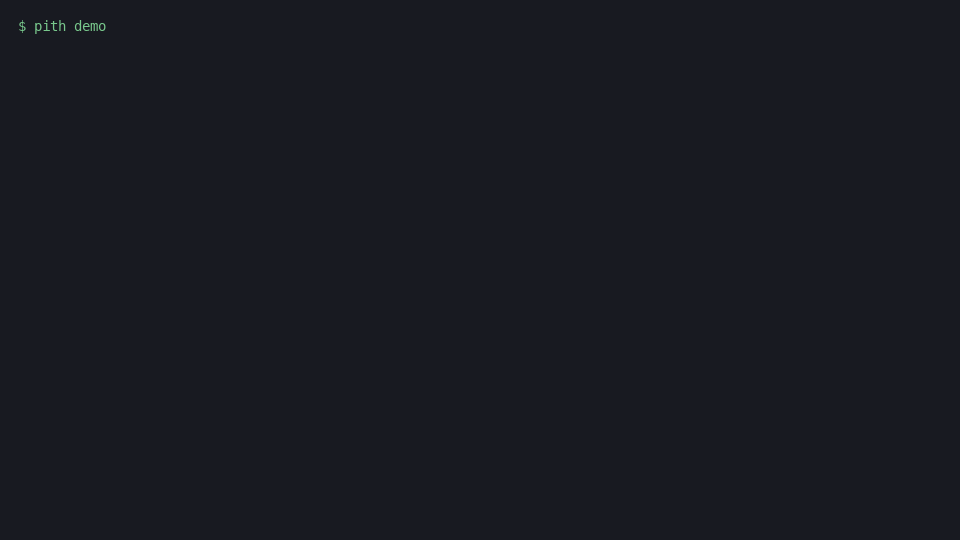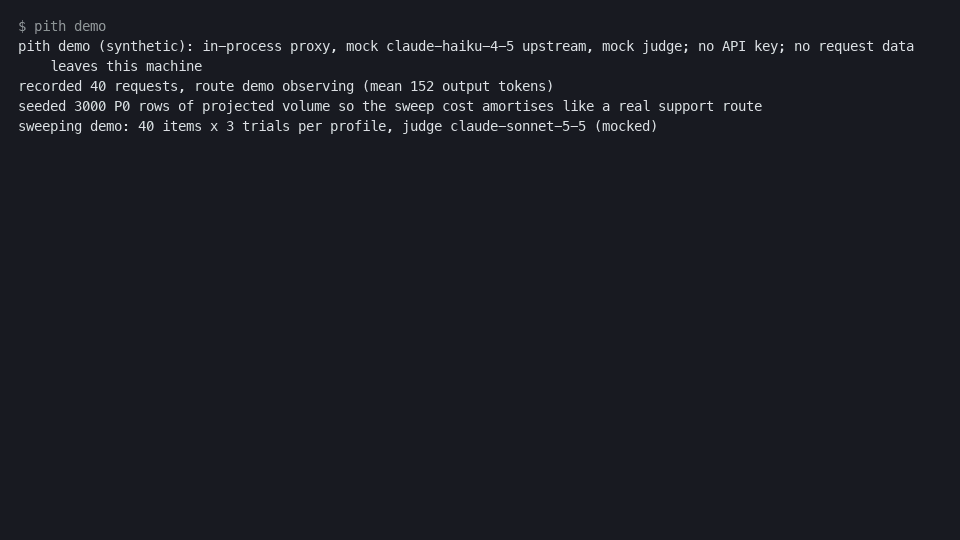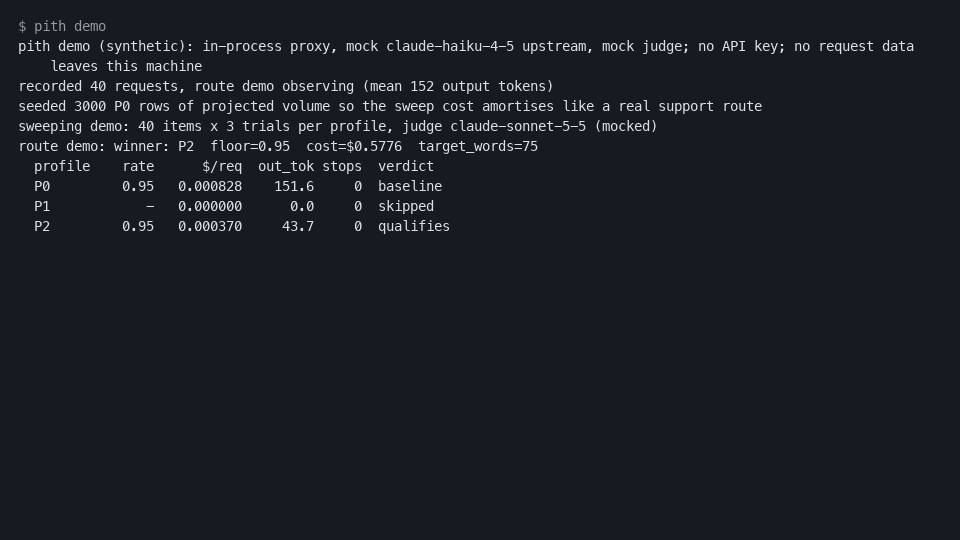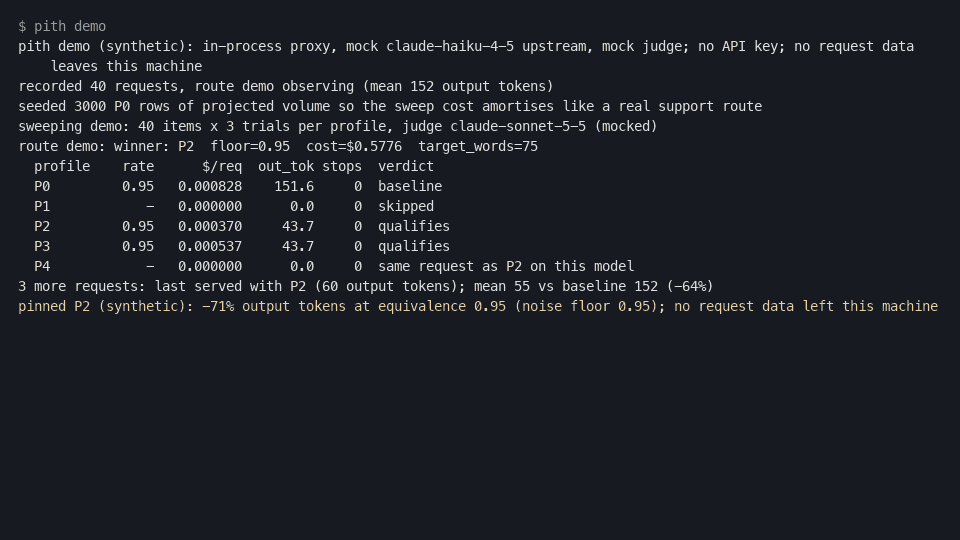
pip install pith-optimizer && pith demo
The demo runs the whole loop in-process against a mock model and a mock judge, with no API key and no data leaving the machine. Its numbers are synthetic. The measured ones are below.
Ten live runs on the Anthropic API, 200 prompts each unless noted, three trials per prompt, judge claude-sonnet-5-5.
"Floor" is how often the unconstrained model agrees with itself, which is the bar a candidate has to meet.
| Route | Model | Best candidate | Outcome | Sweep cost |
|---|---|---|---|---|
| Support tickets, 10 repeated, 30 requests | Haiku 4.5 | −51% tokens at the floor | pinned | $1.30 |
| Support tickets, 200 distinct | Haiku 4.5 | −53% tokens, 0.78 vs floor 0.83 | refused, below floor | $5.99 |
| Ticket classification | Haiku 4.5 | −44% tokens at the floor | refused, sweep not repaid at 13k requests/month | $2.49 |
| JSON extraction | Haiku 4.5 | −5% tokens | refused, nothing to remove | $2.44 |
| SAMSum summarisation | Haiku 4.5 | −53% tokens, 0.64 vs floor 0.84 | refused, drops information | $5.61 |
| Dolly summarisation | Haiku 4.5 | −55% tokens, 0.45 vs floor 0.77 | refused, drops information | $6.20 |
| Bitext support replies | Haiku 4.5 | −54% tokens, 0.51 vs floor 0.72 | refused, drops information | $6.31 |
| GSM8K | Haiku 5.5 | −35% tokens at the floor | refused, sweep not repaid at 10k requests/month | $4.47 |
| GSM8K | Sonnet 5.5 | −40% tokens at the floor | refused, sweep not repaid at 10k requests/month | $7.13 |
| GSM8K, 25k requests/month | Sonnet 5.5 | −37% tokens, −26% cost | pinned, confirmed on a 30% holdout | $8.38 |
Two lessons, stated in full in docs/results.md. A concision instruction saves tokens by dropping content, and on summaries and support replies the judge catches that every time. An effort step-down on a thinking model saves thinking tokens the task did not need, and then the only question is whether the route's volume repays the sweep. Decision rules and their reasons: docs/methodology.md.
pip install pith-optimizer
pith serve                                    # defaults; or --config pith.toml
pith.toml starts from pith.example.toml.
Point your client at it and keep your own API key:
ANTHROPIC_BASE_URL=http://localhost:8787      # Anthropic SDKs
OPENAI_BASE_URL=http://localhost:8787/v1      # OpenAI SDKs
Sweep from the CLI, which is the only place a provider key lives:
export ANTHROPIC_API_KEY=...                  # and/or OPENAI_API_KEY
pith sweep --config pith.toml --dry-run       # estimate, print, write nothing
pith sweep --config pith.toml --holdout 0.3   # pin the cheapest profile that clears the bar
pith recheck --config pith.toml               # re-judge live traffic, revert on drift
Reports: GET /optimizer/report.html. Every scalar setting is also an OPTIMIZER_<FIELD> environment variable.
Full flag reference: docs/sweeps.md.
- Fingerprint. Requests are grouped into routes by provider, model and system prompt.
- Record. Usage and a sample of bodies go into one SQLite file. Nothing is rewritten yet.
- Replay. Once a route has 50 sampled requests, the sweep replays them under each profile: effort one step down, a concision instruction appended as user text, the instruction plus a one-line exemplar, or both levers.
- Judge. A judge model labels every candidate answer against the baseline answer. Every pair of baseline answers is judged too, which gives the floor.
- Pin. The cheapest profile that matches the floor within sampling error, confirmed on a holdout if one was requested, and whose saving repays the sweep within a month, is pinned. Everything else is refused with a reason.
Rewrites never touch the system prompt or tools, so prompt caches keep hitting. Pins are tied to the instruction text they were validated under and drop after an upgrade that changes it.
One SQLite, one sweep CLI, four ways to put it in front of traffic. All honour X-Optimizer: off|bypass and
X-Optimizer-Route, fail open on any pith error, and never log exception text. Pick one per route.
| Standalone proxy | LiteLLM | Headroom | Portkey | |
|---|---|---|---|---|
| Attaches as | pith serve |
guardrail in config.yaml |
two extensions, enabled by env | default.webhook hooks |
| Profiles | effort and concision | concision | effort and concision | concision |
| Streams recorded | yes | yes | yes | no |
| Sweeps go through | provider APIs | the LiteLLM proxy | provider APIs | the Portkey gateway |
Add pith.guardrail.PithGuardrail as a guardrail with mode: [pre_call, post_call]. It records every chat
completion and appends the pinned instruction to the last user message. Setup, keys and limits:
docs/litellm.md.
HEADROOM_PROXY_EXTENSIONS=pith HEADROOM_PIPELINE_EXTENSIONS=pith headroom proxy. The proxy extension records and
rewrites effort, the pipeline extension appends the instruction after compression. Keep Headroom's cache and output
shaper off while pins are in use: docs/headroom.md.
Two default.webhook hooks in the Portkey config call POST /optimizer/portkey on a running pith serve. OpenAI
format only, streams are not recorded, and the endpoint needs webhook_token when it is reachable beyond the
gateway: docs/portkey.md.
- Per request:
X-Optimizer: offforces the baseline.X-Optimizer: bypassalso skips recording. - Per route:
[routes."<key>"] enabled = falseinpith.toml. - Global:
OPTIMIZER_ENABLED=0.
Any pith-side failure forwards the original request unchanged. The proxy has no authentication of its own, so bind
listen to a private interface.
pip install -e '.[dev]' && pytest runs the offline suite. Live tests, the gateway mock tests and the weekly
integrations job are described in docs/development.md.
Design spec: docs/design/specs.
MIT, see LICENSE.